AI Project: OCR-Free Document Parsing with Donut (Vision-to-JSON)
In Document QA Project, we used LayoutLM to read documents. But that required a separate OCR step to find the text first. Now, Hugging Face…
In Document QA Project, we used LayoutLM to read documents. But that required a separate OCR step to find the text first. Now, Hugging Face…
We’ve generated images from scratch, but what about fixing old ones? Hugging Face Image Upscaling offers a powerful solution for this. Super Resolution is the…
We’ve taught AI to classify objects and segment pixels. Now, let’s explore Hugging Face Depth Estimation and teach AI to understand distance. Depth Estimation models…
We’ve generated audio and transcribed files. Now, let’s do it live with a Python Voice Assistant. We will build a script that: Step 1: Installation…
We’ve done Image Captioning (getting a simple description). But what if you want to have a conversation about an image? That’s where Hugging Face LLaVA…
We have generated images, video, and speech. The final frontier of generative media is Music. let’s explore Text to Music Python and see how text…
We’ve generated text, audio, and images. The final frontier is Video. Now, Hugging Face Text to Video technology is opening up exciting new possibilities for…
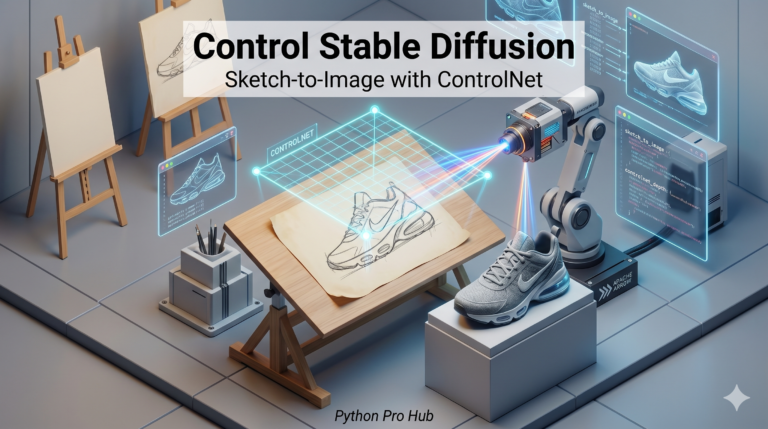
Standard Stable Diffusion is amazing, but it’s chaotic. You type “cat,” and you get a cat, but maybe not the cat pose you wanted. Hugging…
In Fine-Tuning (Part 3: Evaluation & Sharing), we fine-tuned a small BERT model. But if you try to fine-tune a modern LLM (like Llama 3…
So far, we’ve used load_dataset to pull pre-made datasets (like “imdb“) from the Hugging Face Hub. But the real power is training an AI on…